
A/B test subject, content and send time
An A/B test sends two or three versions of a campaign to a sample of its audience and sends the version with the better result to everyone else. Use it for A/B testing email subject lines, the email’s content or the time it goes out.
Before you begin
Section titled “Before you begin”- Setting up a test needs
campaigns:edit; reading the result needsreports:view. - A/B tests are part of regular email campaigns. Recurring digests and SMS, push and WhatsApp campaigns don’t have them.
- Set the campaign’s audience first: the sample is a share of it. A test works best on a large audience; with a few hundred recipients the sample is too small to tell the versions apart.
How a test runs
Section titled “How a test runs”- When the send starts, ReputeCast takes the sample share of the audience and splits it about evenly across the variants. With a 20% sample and two variants, about 10% get A and 10% get B. The sample is picked by contact, not at random per send: with the same sample size, the same contacts are in the sample of every test.
- Everyone else waits. The live monitor counts them as waiting.
- When the test window ends (2 hours after the sample went out), the variant with the higher rate wins: human opens per delivered message, or clicks per delivered message. Machine opens, such as Apple Mail Privacy Protection prefetches, never count.
- The winner goes to everyone who was waiting.
The winner is the higher rate at the end of the window, even when the difference is small enough to be chance. On a tie, the earlier variant (A, then B) wins. The report tells you afterwards whether the difference was significant.
Set up a test
Section titled “Set up a test”-
Open the campaign in the composer and select Preview. In the side panel, find A/B variants and select Set up.
On the canvas, the + button next to Variant A starts a subject test in one step (Start an A/B test).
-
Pick what the variants differ in:
- For a Subject line test, write a second (and third) subject. Everything else stays the same.
- For a Content test, the body is copied as variant B. Switch the canvas to B and edit it. Route and audience stay shared.
- For a Send time test, the variants are the same email at different times, 09:00 and 14:00 by default.
-
Select Add variant for a third variant, C. A test has two or three variants.
-
Set Sample size: 10%, 20% (the default), 30%, 40% or 50% of the audience. Each option shows the number of recipients.
-
Set Winner by: human opens or clicks after 2 hours.
-
Select Review & send. Send Readiness shows the test, for example “A/B subject test” with “20% sample · winner at 12:00”, and the confirmation step lists it before you send.
To remove the test, select Stop testing. Changing or removing a test is recorded in the version history. If the campaign was already approved, changing the test sends it back for approval.
Send-time tests
Section titled “Send-time tests”The times of a send-time test are in the workspace’s time zone, not each recipient’s own, although the panel says recipient-local time. A time that has already passed when the send starts moves to the next day. The Use the best time per recipient instead option in this panel has no effect on sending in this build; to send each contact at their best hour, choose that in Schedule and send a campaign instead of running a send-time test.
Manual pick
Section titled “Manual pick”Manual pick holds the rest of the audience until someone picks the winner. Once the sample has gone out, the campaign’s status turns to Auto-paused while it waits. The app has no button to pick the winner: use the pick A/B winner API operation, which needs campaigns:send. Prefer human opens or clicks unless you have a script ready to choose.
Read the result
Section titled “Read the result”Open the campaign’s report. The A/B card is the last card on the page.
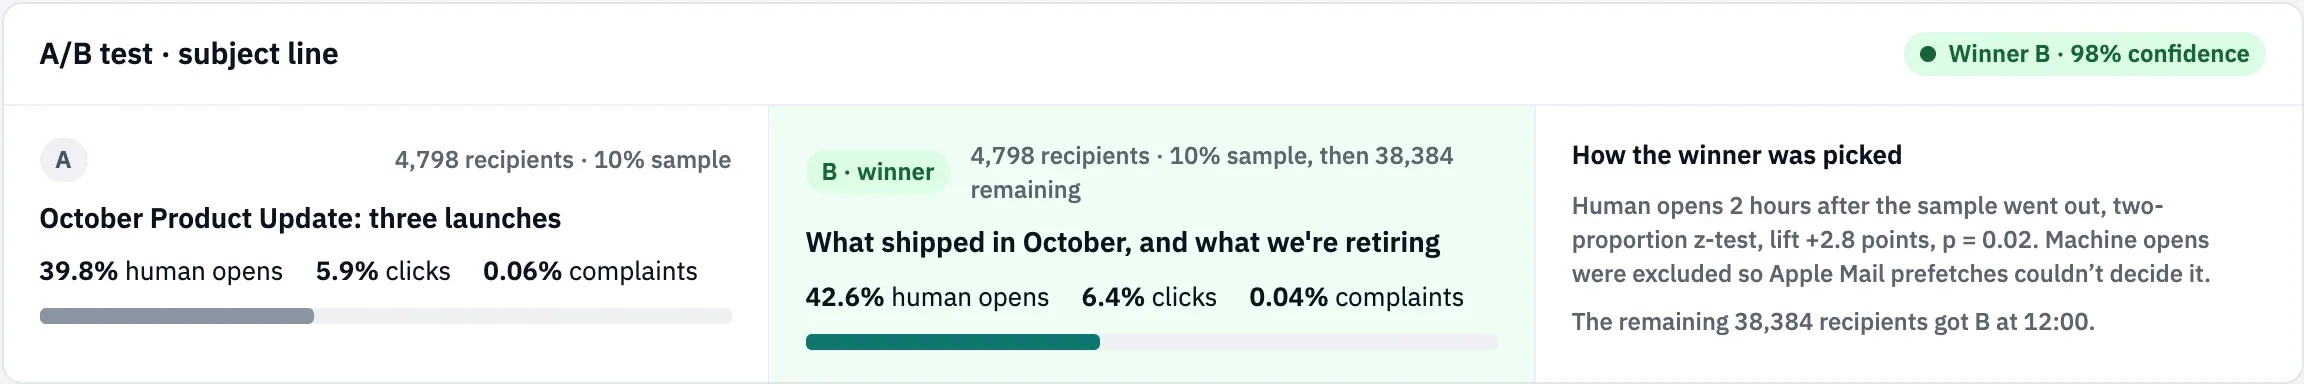
For each variant the card shows its subject (or content or send time), recipients and sample share, human opens, clicks and complaints. The badge says how far to trust the result:
| Badge | Meaning |
|---|---|
| Testing · decides at … | The window is still open. |
| Winner B · 98% confidence | B won and the difference is significant: a two-proportion z-test gives p below 0.05. |
| B chosen · not significant | B had the higher rate and was sent, but the difference could be chance. |
| Not significant yet | No winner is stored, for example a manual-pick test nobody has decided. |
How the winner was picked explains the decision, for example “Human opens 2 hours after the sample went out, two-proportion z-test, lift +2.8 points, p = 0.02”, and when the rest went out. The test compares the leader with the runner-up, so with three variants the third one doesn’t enter the calculation. The numbers keep updating as late opens and clicks arrive, so the confidence can change after the decision.
The same result appears in the live monitor while the test runs (“variant B leading”), under the campaign’s name in the campaigns list, and in the report’s CSV export.
Defaults and limits
Section titled “Defaults and limits”| Setting | Default | How to change |
|---|---|---|
| Campaigns per page | 25 | Fixed in the app; API pageSize, 1–100 |
| Variants in an A/B test | 2 or 3 (A, B, C) | Composer › A/B variants |
| A/B test sample size | 20% of the audience | Composer › A/B variants › Sample size, 10–50%; the API accepts 5–50% |
| A/B test duration before the winner goes to the rest | 2 hours | API durationHours, 1–72 |
| A/B winner chosen by | Human opens | Composer › A/B variants › Winner by; human opens, clicks or manual pick |
| Significance shown in the report (two-proportion z-test) | p below 0.05 | Fixed; at the end of the window the variant with the higher rate is sent either way |
| Recipients of a test send | Up to 10 addresses | Fixed; members without campaigns:send can send tests only to themselves |
Check that it worked
Section titled “Check that it worked”- The canvas shows a Variant switch with A and B (and C).
- Send Readiness shows the test with its sample and winner time.
- After the window, the report’s A/B card names the winner and the remaining recipients who got it.
Troubleshooting
Section titled “Troubleshooting”- No A/B option. The campaign is a recurring digest, or your role lacks
campaigns:edit. - The test always picks A. Neither variant had any human opens or clicks when the window ended, so A won the tie. Use a larger sample, or test on clicks for an audience that rarely opens.
- “Write a subject for variant B”. A subject test needs a subject for every variant.
- The report says not significant. The difference is small for the sample size. Use a larger sample next time, or test a bigger change.
- The rest of the audience never got the email. The test uses manual pick; pick the winner through the API.